Deterministic engine
Fitness, fatigue, form, zones, fueling targets, readiness, and load projections are computed in a pure science layer — unit-tested against literature-minded values, not improvised in a prompt.
Science
We don’t believe in black-box coaching. Koyaro separates the sports-science engine from the conversational layer so every recommendation stays inspectable, adaptable, and honest about uncertainty.
Fitness, fatigue, form, zones, fueling targets, readiness, and load projections are computed in a pure science layer — unit-tested against literature-minded values, not improvised in a prompt.
The language layer helps you plan, fuel, recover, and race — but it is not allowed to invent metrics. When Koyaro answers “why?”, it cites the engine.
Nutrition (including energy-availability awareness), wellness, strength, mobility, and compliance sit beside power data so the prescription reflects the athlete you actually are today.
Overreaching and low energy availability are not growth hacks. The system is designed to surface when less training is the smart call — and to show the signals behind that call.
In the product
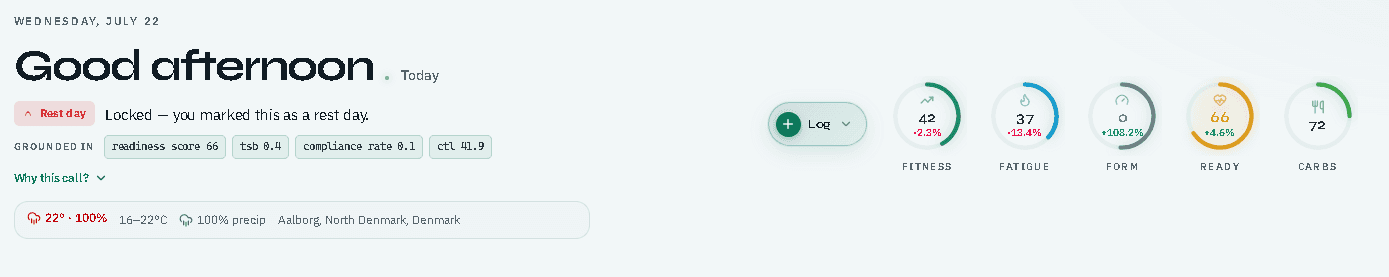
Daily calls, ride analysis, and race tactics are not decorative AI. They expose the grounded metrics — readiness, TSB, CTL, compliance, time in zones — so trust is earned in the UI, not claimed in a tagline.
Methods note
Short list of shipped models — not a literature review. Each number below is owned by the science engine; the AI layer can cite it, not invent it. Full release history lives on the changelog.
DecidesWhether form supports hard work, taper, or recovery — and how load accumulates over weeks.
ModelCoggan Performance Manager Chart (PMC) for athlete-facing CTL / ATL / TSB. Optional Banister impulse-response (Banister / Calvert (1975 / 1976)) for research-grade performance projection from the same daily load.
The conversational layer cannot invent this number — it only narrates what the engine already computed.
DecidesHow much of your pedaling time should sit easy, mid, and hard — and whether the week matched the philosophy you chose.
ModelPolarized vs pyramidal vs threshold on a 3-zone model (time-in-zone, not session count). Pyramidal is the catalog default (ADR-0012). Seiler-style polarized / pyramidal TID (Seiler & Kjerland 2006; Seiler 2010).
The conversational layer cannot invent this number — it only narrates what the engine already computed.
DecidesWhere easy ends, where hard begins, and how realized TID is scored when lab or field thresholds exist.
ModelIntensity-domain anchors: LT1 / VT1 and LT2 / VT2 when measured; CP as the hard-boundary proxy when LT2 is unset; FTP × 0.75 / 0.90 as FTP-only fallback. Seiler 3-zone framing (Seiler 2010).
The conversational layer cannot invent this number — it only narrates what the engine already computed.
DecidesAnaerobic reserve left on a climb or in a surge, interval design that does not empty W′, and race effort budgets.
ModelAthlete CP / W′ anchors with Skiba W′bal (ODE form; Skiba et al. 2012; Clarke et al. 2021 reference behavior).
The conversational layer cannot invent this number — it only narrates what the engine already computed.
DecidesAccepted threshold power and the Coggan power zones rebuilt from it — without inventing watts in chat.
ModelAllen & Coggan 20-min × 0.95; Carmichael Training Systems 2×8-min × 0.90; TrainerRoad-style ramp × 0.75 of peak 1-min / MAP (coaching conventions — no journal DOI).
The conversational layer cannot invent this number — it only narrates what the engine already computed.
DecidesTraining load and heart-rate zones when power is missing — so PMC and planning still have a number.
ModelhrTSS when LTHR is set; otherwise per-sample Banister TRIMP (Banister / Calvert (1975 / 1976)). Optional Karvonen %HRR zones (Karvonen et al. 1957) when max and rest HR are known.
The conversational layer cannot invent this number — it only narrates what the engine already computed.
DecidesHow much power you keep after prior work — for ride review, race demands, and progression over multi-kJ windows — and when to prescribe race-pace under fatigue.
ModelDurability v2: multi-kJ thresholds × multi-duration MMP with prior-intensity context (Spragg et al. 2024; Pinot & Grappe; Maunder durability review). Fatigued CP after prior work with optional CHO attenuation (Norte 2026 CHO × fatigued CP; Clark 2019 fatigued CP/W′; W′ unprotected). Prescribe resilience sessions as prior work below LT2 then late quality (Jones & Kirby 2025; Spragg 2023 durability characteristics) — best available / emerging, not proven % gains.
The conversational layer cannot invent this number — it only narrates what the engine already computed.
DecidesDaily CHO targets by training load, and grams-per-hour bands during long or race efforts.
Model“Fuel for the work required” daily bands (ACSM 2016; Burke 2011; Impey 2018). In-ride ACSM duration bands up to 90 g/h, with optional 100–120 g/h only when gut-trained / race prefs justify it (Jeukendrup). Session CHO/EE burn from TSS when VT2 VO₂ and load covariates are known (Rothschild 2025) — distinct from target g/h.
The conversational layer cannot invent this number — it only narrates what the engine already computed.
DecidesWhen low energy availability should caution or protect the prescription — ease intensity or remove hard work.
ModelLoucks EA bands plus IOC 2023 REDs adaptable vs problematic LEA framing (Mountjoy et al., BJSM 2023). Engine screening only — not a clinical diagnosis or IOC REDs CAT2.
The conversational layer cannot invent this number — it only narrates what the engine already computed.
Deeper in-product science articles are a separate surface. For the athlete-facing stance, read science stance. For why recommendations must cite the engine, read why every recommendation has to show its work. Or continue with our story or what’s shipping.
Join the waitlist and interrogate the first daily call when you’re invited — that is the demo.